Voice science stands at a monumental technological and clinical crossroads. Today, artificial intelligence (AI) and machine learning (ML) are fundamentally reshaping how researchers conduct investigations, how clinicians analyze complex acoustic data, and how medical professionals care for patients. This digital transformation is not a sudden, accidental disruption; rather, it is the culmination of decades of careful, multidisciplinary research bridging the physical, biological, and computational sciences.
At the center of this evolution is The Voice Foundation and its premier peer-reviewed publication, the Journal of Voice. Long before mainstream consciousness grasped the capabilities of neural networks or large language models, visionary researchers were already leveraging computational tools to decode the mysteries of human vocalization.
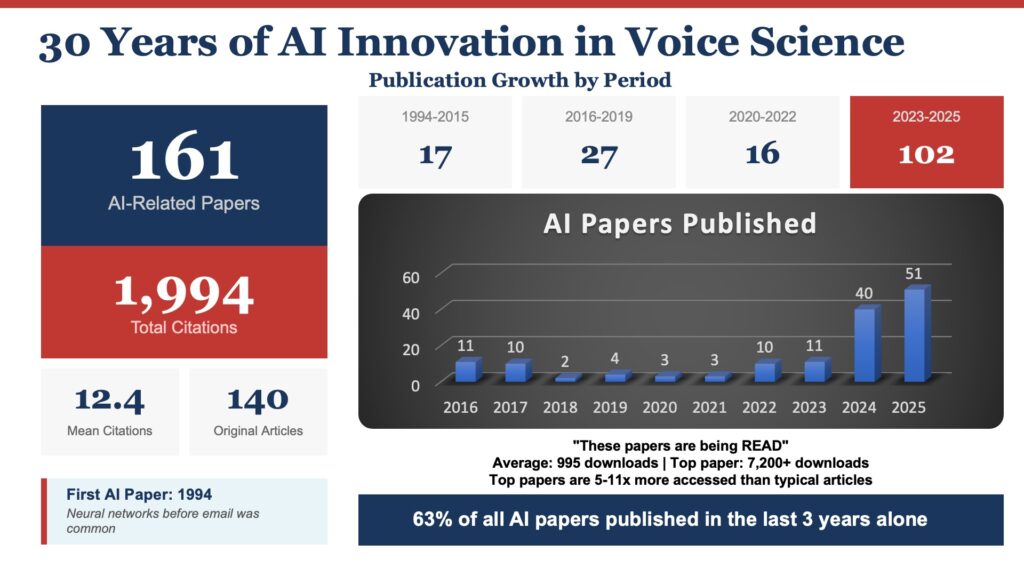
Recent publishing metrics underscore a staggering acceleration in this domain. Out of 161 AI-related papers published in the Journal of Voice since its earliest digital-era milestones, an astonishing 102 papers—63 percent—have appeared in just the last three years (2023–2025). In 2025 alone, the journal published 51 AI-centric papers, surpassing the total output of the field’s first twenty years combined. This is no longer gradual scientific progress; it is an exponential transformation that is redefining voice pathology detection, establishing the human voice as a critical digital biomarker for systemic health, and introducing conversational AI directly into clinical decision-making.
A Legacy of Interdisciplinary Innovation
To understand the magnitude of today’s AI-driven revolution, one must first look back at the institutional foundation that made such breakthroughs possible. In 1969, Dr. Wilbur James Gould founded The Voice Foundation in New York City. At a time when interdisciplinary care for the human voice was virtually non-existent, Dr. Gould exhibited groundbreaking foresight. He united physicians, scientists, speech-language pathologists, performing artists, and educators into a single collaborative ecosystem dedicated to the care of the professional voice user.
In 1972, the Foundation hosted its inaugural Annual Symposium—Care of the Professional Voice—followed shortly by its first Gala (later known as Voices of Summer) in 1973. For over five decades, the institution has successfully built bridges between art and science, and between the sterile environment of the clinic and the vibrant stage of the performing arts.
Since 1989, the Foundation has been under the visionary leadership of Dr. Robert Thayer Sataloff, an internationally renowned otolaryngologist who is also an accomplished professional singer and conductor. Having authored more than 1,200 publications, including 79 textbooks, Dr. Sataloff guided the Foundation’s relocation to Philadelphia. Under his stewardship, the organization has continually expanded our understanding of human vocal physiology and pathology through rigorous, interdisciplinary scientific research and education.
Today, the annual Philadelphia symposium draws hundreds of medical, scientific, academic, and speech-language professionals, alongside performing artists from across the globe. Concurrently, the Journal of Voice maintains its status as the definitive, peer-reviewed authority dedicated entirely to voice science and medicine.
Detailed Chronology: Thirty Years of AI Research in Voice Science
A common misconception in the broader tech ecosystem is that the intersection of artificial intelligence and medicine is an entirely recent phenomenon born out of the 2020s generative AI boom. However, the archives of the Journal of Voice tell a vastly different story.
The Pioneering Era (1994–2015)
The Journal of Voice has been publishing peer-reviewed AI research longer than most observers realize. In 1994—thirty-one years ago, during the exact same year the World Wide Web was first emerging into public consciousness—the journal published a landmark paper by Rihkanen and colleagues titled "Spectral Pattern Recognition of Improved Voice Quality." This foundational study utilized early neural networks to analyze voice metrics. In short, the voice science community was publishing machine learning research before the vast majority of professionals had ever sent an electronic mail message.
Despite this early entry, progress during the initial decades was measured. Between 1994 and 2015, the journal published 17 AI-focused papers. These early works laid the crucial groundwork, proving that computers could be trained to recognize patterns in acoustic signals that bypassed human perceptual limits.
The Acceleration and Exponential Surge (2016–2025)
As computational power expanded and machine learning architectures matured, publication rates began to climb. Between 2016 and 2019, the journal published 27 AI papers, followed by 16 papers from 2020 to 2022.
Then came the modern inflection point. Between 2023 and 2025, the academic output skyrocketed, with 102 papers published in this compressed three-year window. The annual breakdown highlights the hockey-stick curve of adoption:
1994–2015: 17 papers
2016–2019: 27 papers
2020–2022: 16 papers
2023–2025: 102 papers
2025 alone: 51 papers (surpassing the output of the first two decades combined)
This dramatic shift reflects an entire scientific community pivoting to harness advanced algorithms, deep learning models, and large-scale data processing.
Supporting Context, Metrics, and Real-World Impact
Academic output alone does not capture the true scope of a scientific paradigm shift; real-world consumption and application are the ultimate arbiters of impact. Usage statistics from the Journal of Voice reveal that these AI-related papers are not sitting idly in digital archives—they are being aggressively read, downloaded, and implemented by clinicians and researchers worldwide.
Global Readership and Downloads
On average, an AI-focused paper published in the journal is downloaded nearly 1,000 times. Outliers within this category achieve extraordinary reach:
COVID-19 Detection Study: The most-accessed AI paper in the journal’s history—focusing on machine learning applications for COVID-19 detection—has amassed over 7,200 downloads, representing eleven times the median download rate for typical articles in its issue.
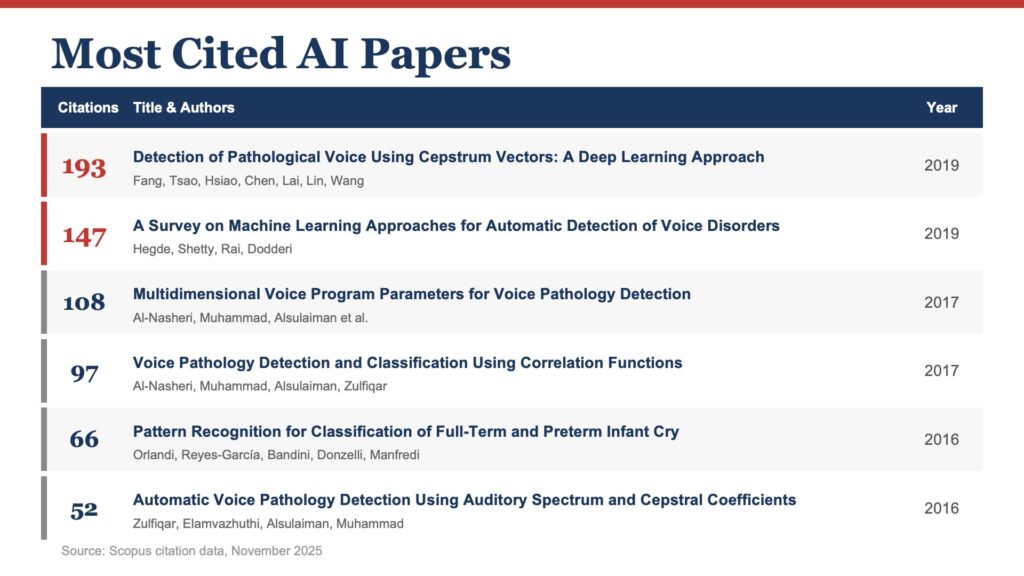
Deep Learning for Voice Pathology (Fang et al.): Garnering 193 citations and nearly 5,000 downloads, this 2019 study on deep neural networks remains the most-cited AI paper in the journal’s history.
Machine Learning Survey (Hegde et al.): With 147 citations and nearly 5,000 downloads, this comprehensive overview serves as an essential onboarding text for researchers entering the field.
Both of these top-cited works were ranked among the top three most-accessed articles in their respective issues. Crucially, these figures do not merely represent academic vanity metrics; they represent clinicians, speech-language pathologists, and biomedical engineers actively seeking practical, technology-driven tools to enhance patient outcomes.
Landmark Research Reshaping Clinical Frontiers
The body of literature published in the Journal of Voice spans several distinct yet interconnected technological milestones:
Pathology Detection via Deep Learning: Following Fang et al.’s pioneering 2019 work on cepstrum vectors and deep neural networks, subsequent researchers pushed the envelope further. Studies by Chen and Chen (2022) on deep neural networks for voice classification, Fujimura’s exploration of one-dimensional convolutional neural networks (CNNs), and Cho and Choi’s comparative analysis of CNN models for laryngoscopic images have systematically dismantled historical diagnostic limitations.
The Voice as a Digital Biomarker: Perhaps the most profound paradigm shift is the recognition of the human voice as a non-invasive digital biomarker for systemic health. Hemmerling and Wójcik-Pędziwiatr’s 2022 paper on predicting Parkinson’s disease severity from voice signals has secured 29 citations in three years, steering research closer to routine clinical implementation. Furthermore, emerging systematic reviews examine voice quality markers for depression and bipolar disorder, opening pathways for continuous mental health monitoring that could alleviate overstretched clinical infrastructures.
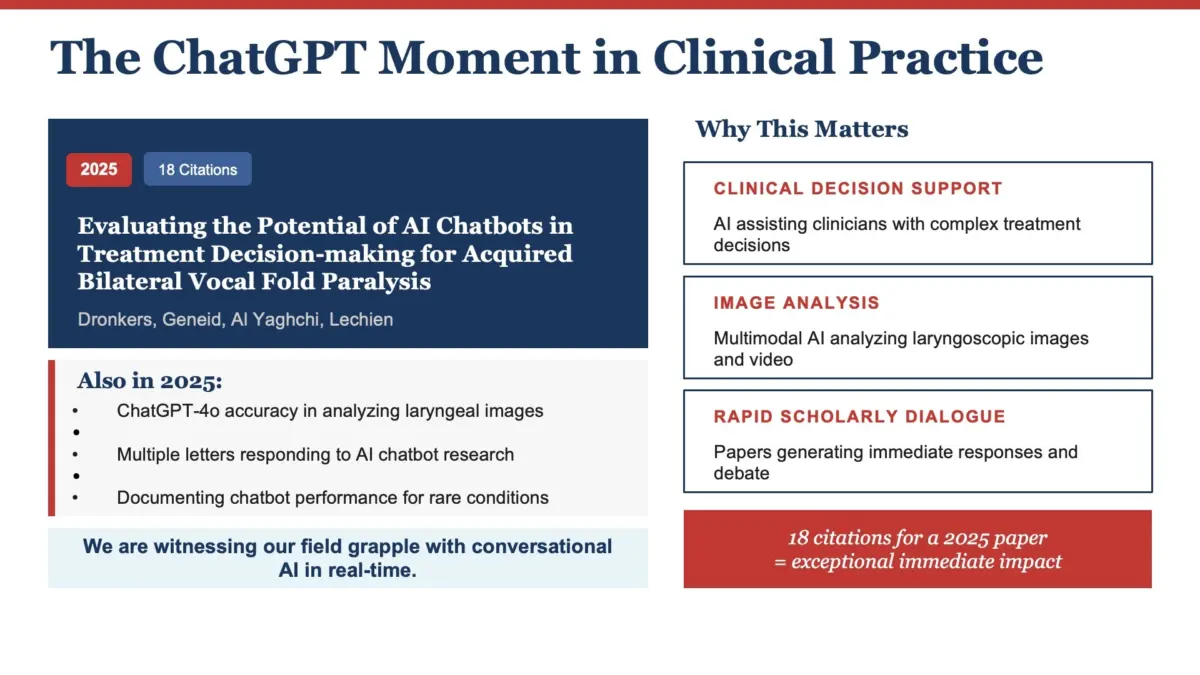
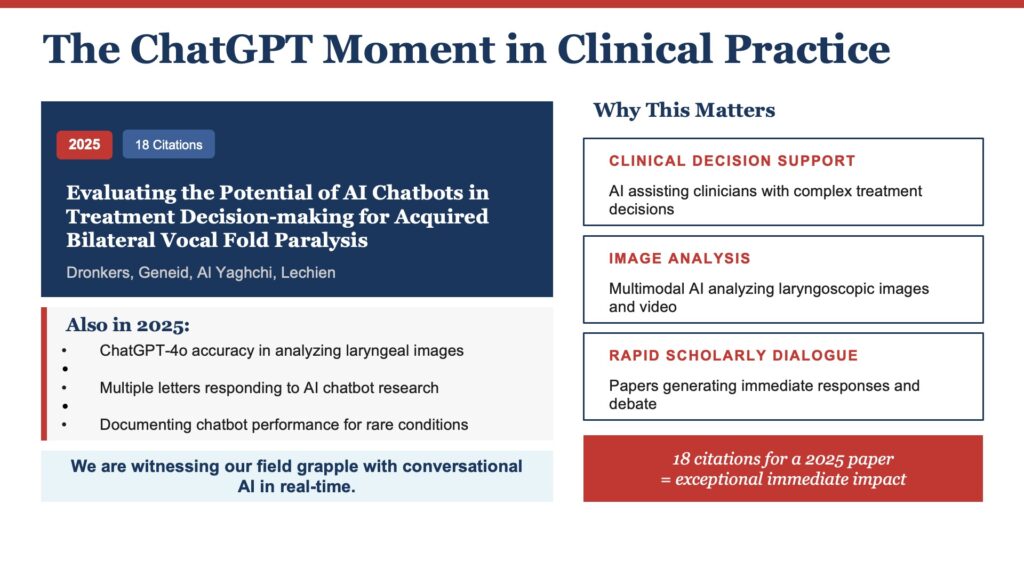
Conversational AI in Clinical Workflows: In 2025, the journal expanded into the evaluation of large language models and AI chatbots in clinical decision-making. Dronkers and colleagues’ paper on "Evaluating the Potential of AI Chatbots in Treatment Decision-making for Acquired Bilateral Vocal Fold Paralysis" quickly accumulated 18 citations—an extraordinary velocity for a paper published within the same calendar year. Accompanying letters to the editor and response papers evaluating tools like ChatGPT-4o’s accuracy in laryngeal image analysis demonstrate a medical field actively grappling with the realities of conversational AI.
Official Perspectives: Expert Insights on AI Integration
To navigate this rapidly evolving landscape, the voice science community relies on the wisdom of interdisciplinary leaders who understand both the computational underpinnings and the clinical realities of voice care.
Dr. Mark Berardi: Managing Complexity and Synthetic Communication
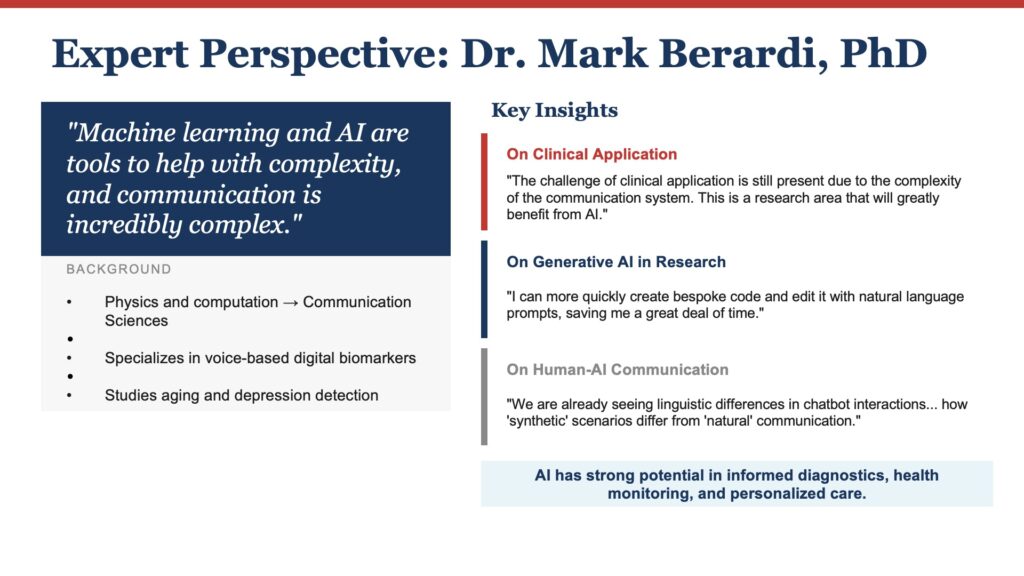
Drawing from a background in physics and computation, Dr. Mark Berardi views artificial intelligence fundamentally as a mechanism for managing complexity.
"Machine learning and AI are tools to help with complexity, and communication is incredibly complex in its neurobiological and physiological processes. So I think the application is warranted," Dr. Berardi notes.
His research zeroes in on voice-based digital biomarkers for aging and depression. While acquiring voice signals has become technically straightforward, the true challenge remains the intricate nature of human communication itself—an arena where AI excels. Regarding generative AI, Dr. Berardi offers a pragmatic appraisal. While it may not have entirely rewritten foundational research paradigms overnight, it successfully eliminates operational bottlenecks, allowing researchers to rapidly draft bespoke code and manipulate datasets via natural language prompts.
Intriguingly, Dr. Berardi’s work also investigates human-AI communication dynamics: how humans alter their speech patterns when interacting with conversational agents versus fellow humans, and how synthetic environments like video conferencing alter verbal behavior. "We are already seeing linguistic differences in chatbot interactions," he observes, suggesting that future voice science must encompass not just human-to-human vocalization, but human-to-machine discourse as well.
Dr. Eric Hunter: Embracing Change with Ethical Clarity
Dr. Eric Hunter focuses heavily on the institutional and operational realities of integrating AI into academia and clinical practice.
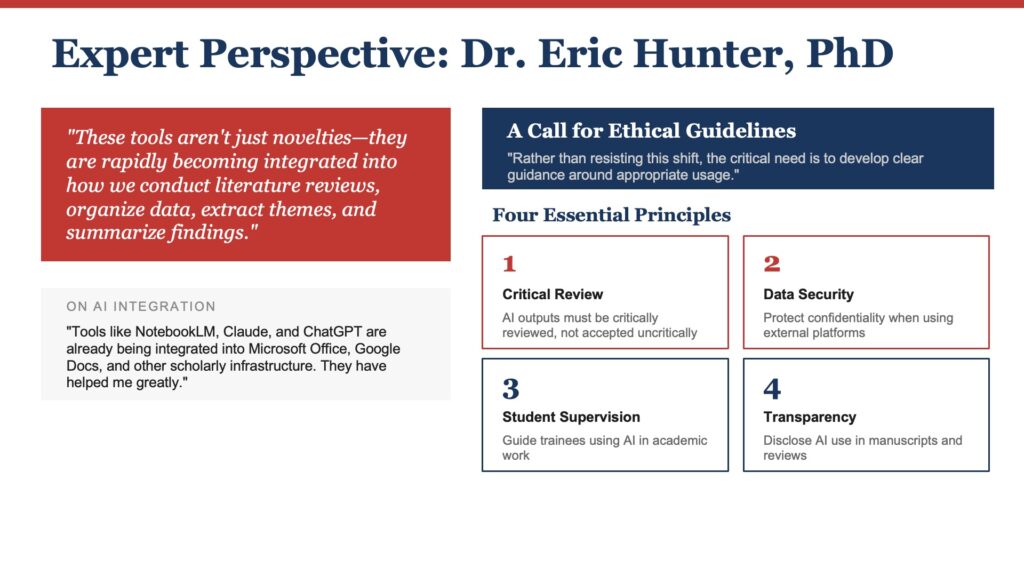
"These tools aren’t just novelties," Dr. Hunter warns. "They are rapidly becoming integrated into how we conduct literature reviews, organize data, extract themes from large bodies of text, and even summarize findings."
He stresses that large language models and machine learning pipelines are permanent fixtures of the modern academic workflow. Rather than fighting an inevitable tide, Dr. Hunter issues a vital call to action for the scientific community: establish clear, transparent guidance regarding appropriate usage for both authors and reviewers.
To maintain scientific integrity amidst this automation wave, Dr. Hunter advocates for a balanced framework that embraces productivity-enhancing tools while strictly upholding human accountability, transparency in data handling, and rigorous peer review oversight. "Our field will benefit most," he concludes, "if we embrace the productivity these tools offer while also building a shared ethical framework for their responsible use."
A Global Research Community
The architectural backbone of this scientific renaissance is not confined to a single elite university laboratory or a solitary corporate R&D department. The AI voice research community documented within the Journal of Voice is profoundly global, interdisciplinary, and collaborative.
Leading authors and foundational contributors steering this movement include:
Jérémie René Lechien (6 papers)
Dimitar Deliyski (5 papers)
Stephanie Zacharias (5 papers)
Ahmed Yousef (4 papers as first author)
Paavo Alku, Leonardo Wanderley Lopes, and Maryam Naghibolhosseini (4 papers each)
Supported by dozens of research groups spanning every inhabited continent, these scholars are collectively validating machine learning models against vast clinical datasets, ensuring that computational voice science is robust, reproducible, and universally applicable.
Future Outlook and the Path Forward
As the Journal of Voice looks toward the next decade, its editorial mission remains resolute: publishing uncompromising, rigorous research that pushes scientific boundaries while preserving the highest standards of academic integrity. However, realizing the full promise of artificial intelligence requires coordinated, collective action across three distinct pillars:
Mindful Engagement with Technology: Researchers and clinicians must view AI tools not as autonomous decision-makers, but as sophisticated instruments designed to manage complexity. Practitioners must master their capabilities, respect their limitations, and use them to augment—rather than replace—clinical judgment.
Commitment to Ethical Frameworks: As Dr. Eric Hunter emphasizes, building a shared ethical framework is an industry-wide necessity. No single journal or institution can draft these guardrails alone; it demands proactive collaboration among ethicists, computer scientists, physicians, and speech-language pathologists.
Open Scientific Communication: The 161 AI-focused papers published to date represent merely the opening chapter. Clinicians, educators, and laboratory researchers must continue sharing empirical findings, ensuring that the fruits of digital innovation directly benefit patients worldwide.
Conclusion
For hundreds of thousands of years, the human voice has served as our primary instrument of connection, emotional expression, and personal identity. It carries the subtle signatures of our psychological states, our neurological vitality, and our physical health in ways that no other biological signal can match.
Now, for the first time in human history, we possess computational tools sophisticated enough to genuinely decode that complexity. We stand on the cusp of an era where non-invasive acoustic screening can detect neurodegenerative disorders years before clinical symptoms manifest, where AI can extend the reach of expert clinicians to underserved populations, and where voice care is democratized on a global scale.
The Journal of Voice and The Voice Foundation stand proudly at the epicenter of this historic transformation. As the next decade unfolds, the convergence of human artistry and artificial intelligence promises discoveries that will forever alter our understanding of the human voice—and the human condition itself.
About the Author Ian DeNolfo is Executive Director of The Voice Foundation, which publishes the Journal of Voice. A graduate of The Juilliard School and The Curtis Institute of Music, he formerly performed as a leading tenor at opera houses worldwide before transitioning to arts administration and scientific leadership at The Voice Foundation.