
By Ian DeNolfo, Executive Director, The Voice Foundation
We stand today at a profound inflection point in voice science—a historic juncture where artificial intelligence is fundamentally reshaping how we conduct research, analyze complex acoustic data, and deliver patient care. The human voice has served as our primary instrument of connection, expression, and identity for hundreds of thousands of years. It carries our emotions, mirrors our psychological state, and broadcasts our systemic health in ways no other biological signal can match.
Now, for the first time in medical and technological history, we possess computational tools sophisticated enough to decode that complexity. Artificial intelligence is not merely supplementing voice science; it is revolutionizing it, offering unprecedented windows into our brains, bodies, and overall wellbeing. At the center of this transformation stands The Voice Foundation and its premier peer-reviewed publication, the Journal of Voice, chronicling a journey from early interdisciplinary experiments to a roaring, exponential era of machine learning and deep neural networks.
Executive Overview: A Paradigm Shift in Voice Research
The intersection of artificial intelligence and voice science represents one of the most dynamic frontiers in modern medicine. What began decades ago as experimental spectral pattern recognition has exploded into a global, multidisciplinary movement involving neural networks, deep learning architectures, and generative AI models.
This digital transformation is rewriting the rules of clinical diagnostics. Voice is rapidly emerging as a non-invasive digital biomarker—a vital sign capable of flagging neurological decline, tracking mental health trends, and detecting respiratory pathologies long before conventional symptoms manifest.
Yet, this rapid acceleration brings critical challenges. As AI tools weave themselves into the academic and clinical fabric—assisting with literature reviews, data processing, and diagnostic workflows—the voice science community must confront the imperative of ethical oversight. Balancing technological acceleration with academic integrity is the defining challenge of our era. Through it all, The Voice Foundation remains steadfast in its mission: to bridge the gap between art and science, and clinic and stage, ensuring that human expertise remains at the helm of technological progress.
The Voice Foundation: A Legacy of Interdisciplinary Innovation
To understand the magnitude of today’s AI-driven revolution, one must look back at the foundation upon which modern voice science was built. In 1969, Dr. Wilbur James Gould founded The Voice Foundation in New York City. At that time, comprehensive, interdisciplinary care for the human voice was virtually nonexistent. Otolaryngologists rarely collaborated directly with speech-language pathologists, singing teachers, or vocal performers.
Dr. Gould’s groundbreaking foresight shattered these professional silos. He brought together physicians, scientists, speech-language pathologists, performing artists, and educators to share knowledge and optimize the care of professional voice users. In 1972, the Foundation hosted its first Annual Symposium: Care of the Professional Voice, followed closely by its inaugural Gala (later celebrated as Voices of Summer) in 1973. For over five decades, the organization has tirelessly built bridges between art and science, between the clinical laboratory and the theatrical stage.
Since 1989, the Foundation has been guided by Dr. Robert Thayer Sataloff, an internationally renowned otolaryngologist who is simultaneously a professional singer and conductor. Having authored more than 1,200 publications, including 79 textbooks, Dr. Sataloff’s visionary leadership relocated the Foundation to Philadelphia. Under his stewardship, the organization expanded its reach, deepening its commitment to interdisciplinary scientific research and professional education.
Today, the annual Philadelphia Symposium draws hundreds of medical doctors, scientists, academics, speech-language pathologists, and performing artists from every corner of the globe. Alongside this vibrant gathering sits the Journal of Voice—the undisputed premier peer-reviewed journal dedicated exclusively to voice science and otolaryngology.
A Thirty-Year Chronology: AI’s Quiet Beginnings in Voice Science
While public consciousness around artificial intelligence has only recently reached a fever pitch, the readership of the Journal of Voice has been exploring machine learning for over three decades.
Our entry into computational analysis predates the consumer internet. In 1994—thirty-one years ago—the Journal of Voice published a seminal paper by Rihkanen and colleagues titled "Spectral Pattern Recognition of Improved Voice Quality." This pioneering study utilized early neural networks to analyze voice characteristics. It was published during the exact year the World Wide Web was first emerging into public awareness, meaning our field was leveraging artificial intelligence in voice science before the vast majority of professionals had ever sent an electronic mail message.
For many years, however, publication growth was methodical and slow. The historical timeline of AI papers published in the Journal of Voice tells a dramatic story of modern acceleration:
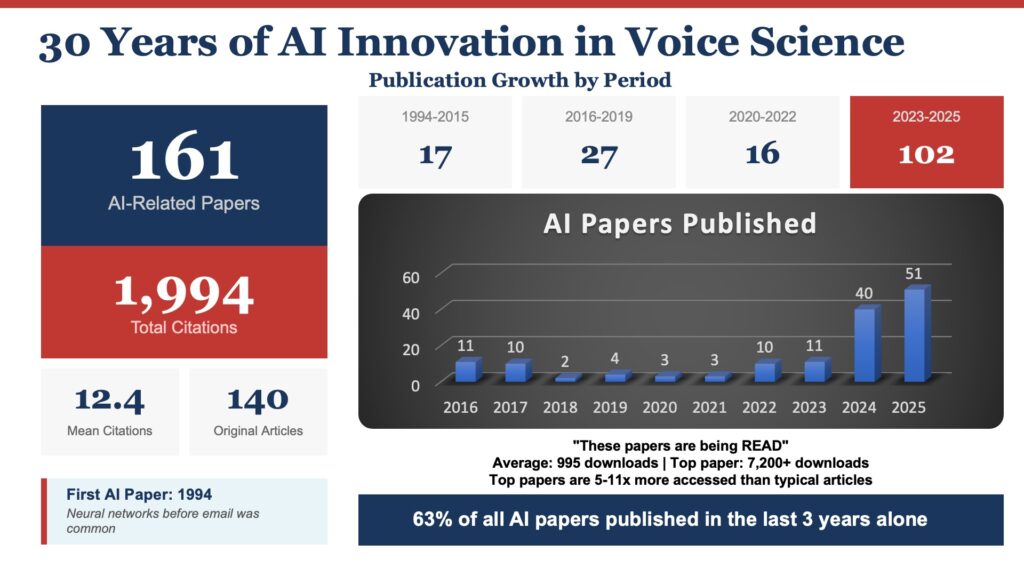
- 1994–2015: 17 papers (The foundational era of early neural network exploration)
- 2016–2019: 27 papers (The rise of machine learning models and advanced feature extraction)
- 2020–2022: 16 papers (Continued refinement during global shifts)
- 2023–2025: 102 papers (The explosive deep learning and generative AI boom)
Consider the most striking statistic of all: 102 out of 161 total historical AI papers—a staggering 63 percent—were published in just the last three years. In the single year of 2025 alone, we published 51 artificial intelligence-related papers. That is more than we published in the entire first two decades of our AI journey combined. This is not gradual, linear growth; this is an exponential transformation of our entire scientific domain.
Supporting Context & Metrics: Beyond Citations to Real-World Impact
Academic metrics can sometimes feel sterile, but in the case of the Journal of Voice, download and citation numbers reflect a profound reality: clinicians, researchers, and speech-language pathologists around the world are actively seeking practical, technological tools to elevate patient care.
The footprint of AI research within our pages is massive:
- The average AI paper in our journal has been downloaded nearly 1,000 times.
- Our most-accessed AI paper—a vital study examining machine learning models for COVID-19 detection—has surpassed 7,200 downloads, scoring eleven times the median rate for articles in its issue.
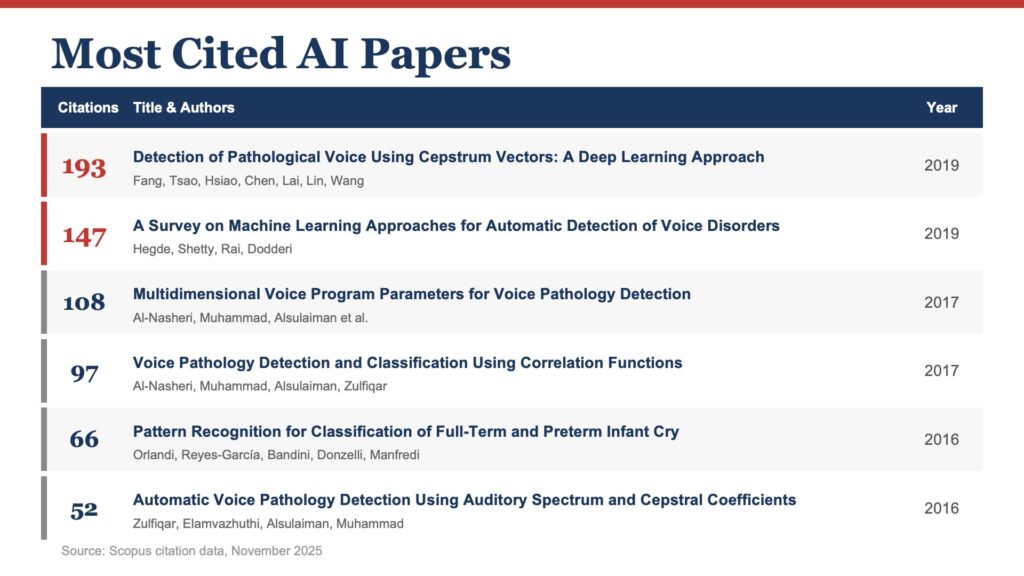
- Our top two most-cited papers (Fang and colleagues’ deep learning study with 193 citations, and Hegde’s machine learning survey with 147 citations) have each been downloaded nearly 5,000 times.
These figures demonstrate that our publications are not sitting idly in digital archives. They are being read by frontline clinicians looking for diagnostic aids and researchers establishing new investigative paradigms.
Landmark Research Shaping the Field
Deep Learning for Voice Pathology Detection
Published in 2019, Fang and colleagues’ paper, "Detection of Pathological Voice Using Cepstrum Vectors: A Deep Learning Approach," remains the most-cited AI paper in our journal’s history. This work proved conclusively that deep neural networks could detect voice pathologies with astonishing accuracy by evaluating acoustic features completely imperceptible to the human ear.
Shortly thereafter, Hegde’s comprehensive "Survey on Machine Learning Approaches for Automatic Detection of Voice Disorders" mapped the theoretical and practical landscape of machine learning, becoming essential reading for newcomers to the field. Contributions by Al-Nasheri et al. (2017) on Multidimensional Voice Program parameters further laid the groundwork for robust automated screening.
The evolution has only accelerated. Subsequent works—such as Chen and Chen’s 2022 research on deep neural networks for voice classification, Fujimura’s exploration of one-dimensional convolutional neural networks, and Cho and Choi’s comparative analysis of CNN models applied to laryngoscopic images—illustrate a field rapidly building upon its own breakthroughs.

Voice as a Digital Biomarker
Perhaps the most transformative concept to emerge from recent research is the validation of the human voice as a digital biomarker—a non-invasive window into systemic, whole-body health.
Groundbreaking studies published in our pages have explored using automated voice analysis to detect and monitor the progression of Parkinson’s disease. For instance, Hemmerling and Wójcik-Pędziwiatr’s 2022 paper on predicting Parkinson’s severity from acoustic signals amassed 29 citations in a mere three years, blazing a trail toward point-of-care clinical applications.
Furthermore, recent systematic reviews have investigated voice quality as a digital biomarker for clinical depression and bipolar disorder. The clinical implications are breathtaking: the prospect of identifying mental health fluctuations via routine voice monitoring could enable early therapeutic intervention and drastically relieve overstretched psychiatric healthcare systems.
AI Chatbots in Clinical Decision-Making
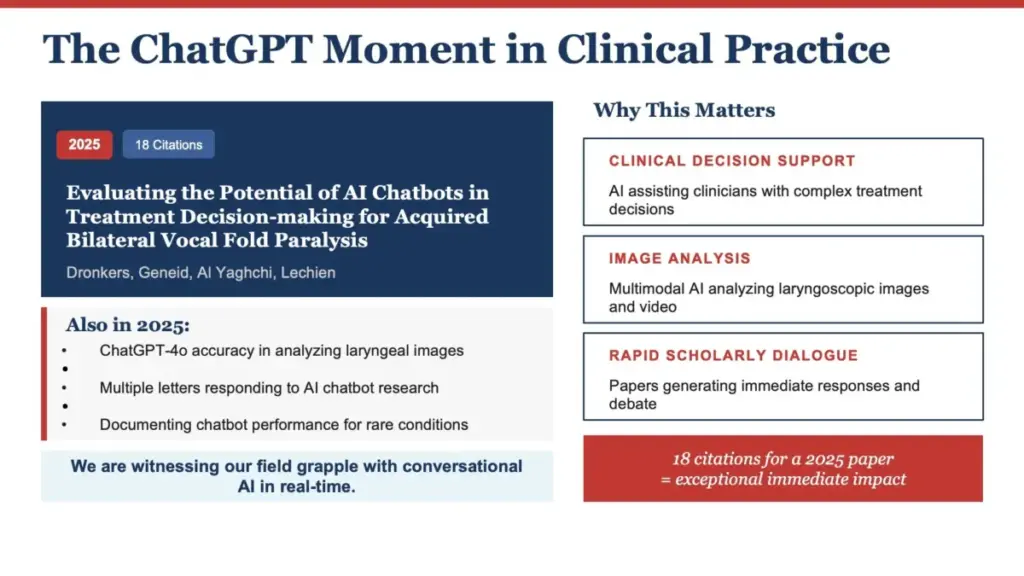
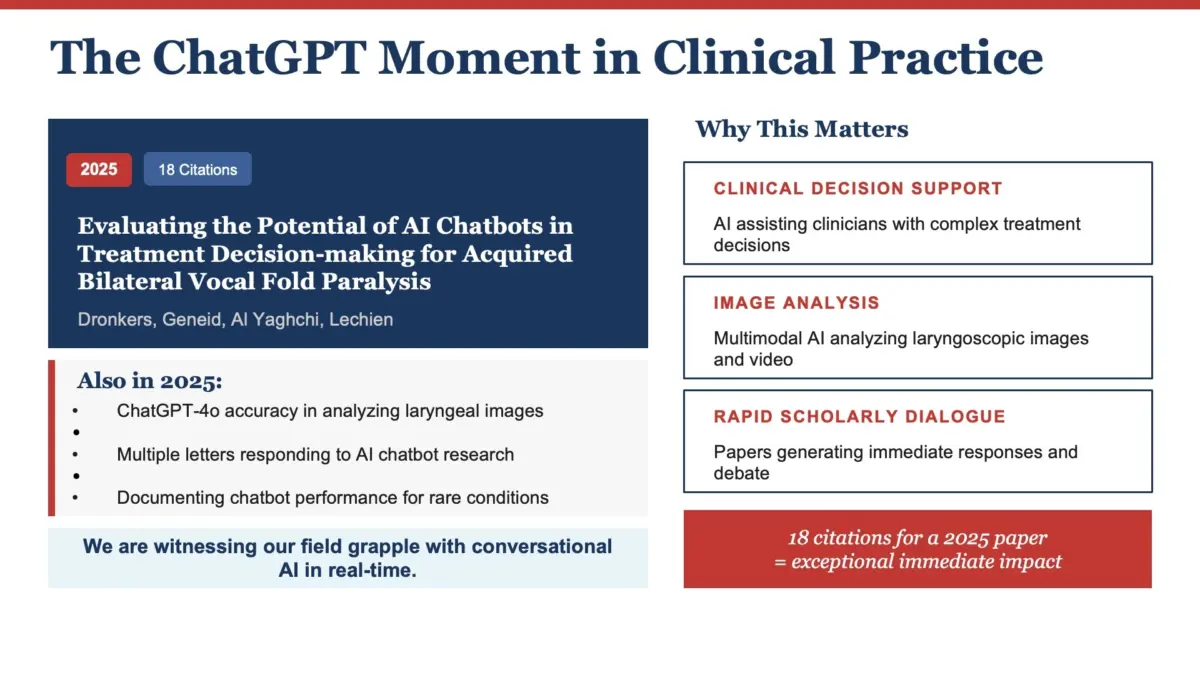
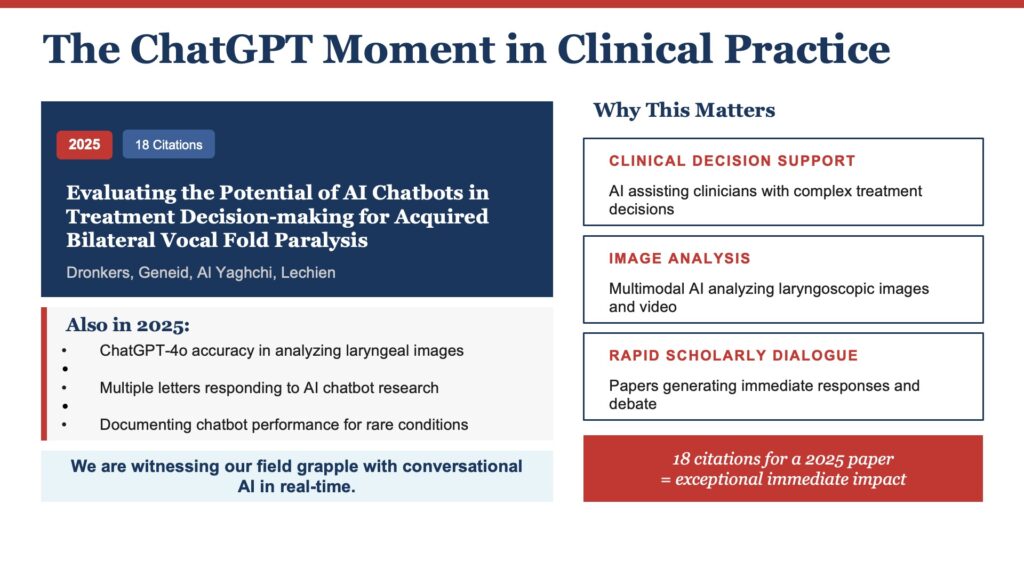
The year 2025 marked a new threshold with the publication of research evaluating conversational AI and large language models in direct clinical workflows. Dronkers and colleagues’ paper, "Evaluating the Potential of AI Chatbots in Treatment Decision-making for Acquired Bilateral Vocal Fold Paralysis," accumulated 18 citations almost immediately upon release, sparking rigorous debate, multiple letters to the editor, and follow-up studies regarding AI accuracy in analyzing complex laryngeal images.
Official Perspectives: Expert Insights on the AI Frontier
To fully capture the sentiment of our scientific community, we turn to leading voices who bridge computational science, clinical practice, and institutional governance.
Dr. Mark Berardi: Managing Biological Complexity
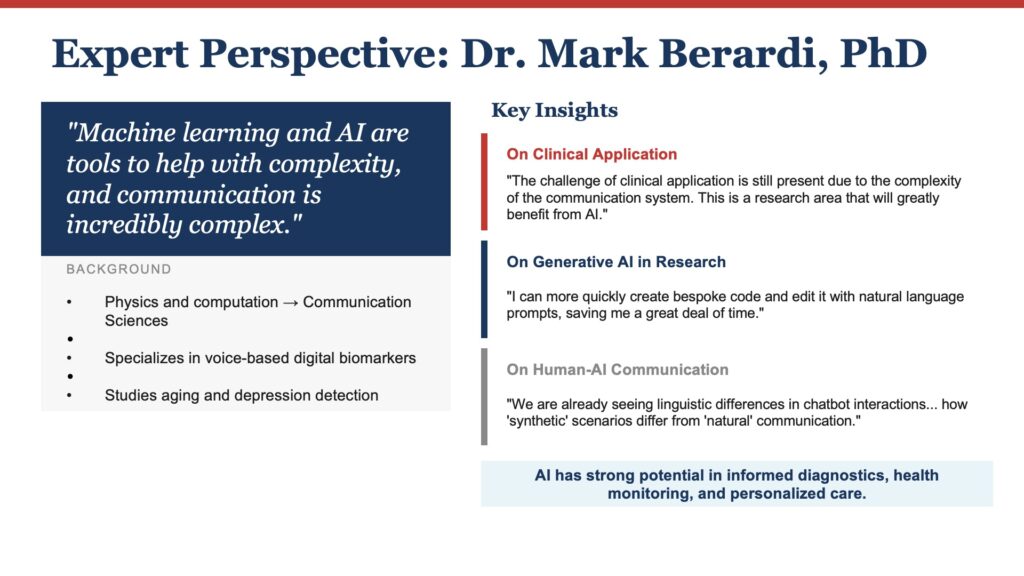
Coming from a background in physics and computation, Dr. Mark Berardi views artificial intelligence through the lens of complexity management. Human communication is an extraordinarily intricate neurobiological and physiological symphony.
"Machine learning and AI are tools to help with complexity, and communication is incredibly complex in its neurobiological and physiological processes. So I think the application is warranted," Dr. Berardi observes.
His research focuses on extracting voice-based digital biomarkers for aging and depression. While acquiring voice signals is becoming seamless, the true hurdle remains the inherent complexity of the human communication apparatus—precisely the domain where machine learning excels.
Regarding generative AI, Dr. Berardi offers a pragmatic, measured assessment. While it may not have rewritten core theoretical physics overnight, it has successfully smashed traditional research bottlenecks. Researchers can now write bespoke data-processing code using natural language prompts.
Intriguingly, Dr. Berardi is also studying human-AI communication dynamics: how humans modify speech patterns when interacting with synthetic chatbots versus other humans, and how remote digital communication (such as Zoom calls) alters vocal behavior. "We are already seeing linguistic differences in chatbot interactions," he notes, suggesting voice science must expand to analyze human speech not just in isolation, but in continuous conversation with machines.
Dr. Eric Hunter: Embracing Change with Ethical Clarity
Dr. Eric Hunter focuses heavily on the institutional and academic implications of AI integration. Generative platforms and large language models are no longer peripheral novelties; they are woven directly into academic workflows.
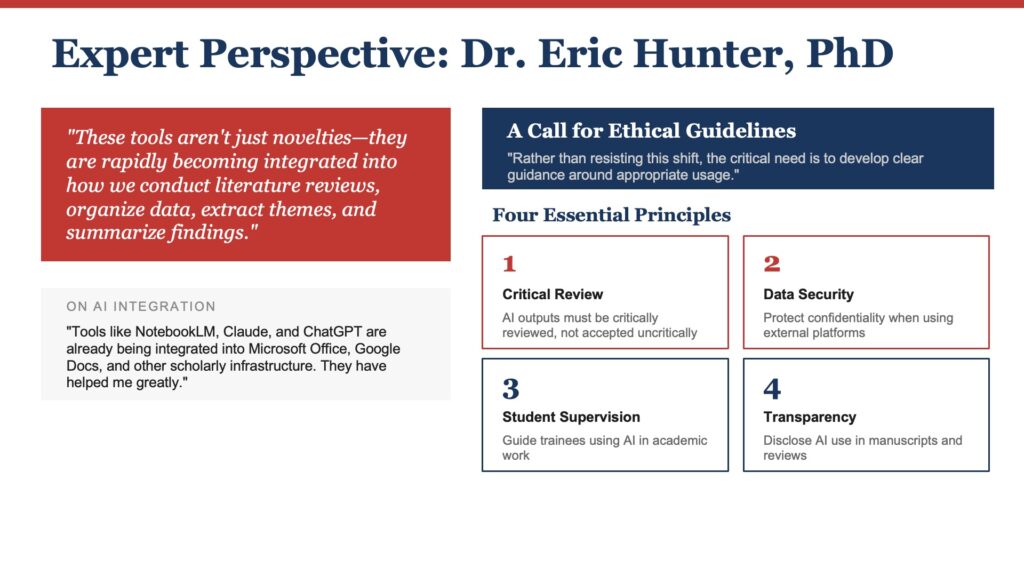
"These tools aren’t just novelties," Dr. Hunter observes. "They are rapidly becoming integrated into how we conduct literature reviews, organize data, extract themes from large bodies of text, and even summarize findings."
As scholarly infrastructure—from Microsoft Office and Google Docs to specialized reference managers—embeds AI natively into its architecture, Dr. Hunter issues a vital call to action for the academic community. Rather than fighting an unwinnable battle of resistance, institutions must establish clear, transparent guidance regarding appropriate usage for authors, peer reviewers, and editors.
Dr. Hunter outlines four foundational pillars for responsible academic AI adoption:
- Absolute Transparency: Full disclosure of any AI tools utilized in drafting, coding, or data synthesis.
- Human Accountability: Researchers must maintain absolute responsibility for the veracity of all data, citations, and analytical conclusions.
- Data Privacy and Security: Rigorous protection of patient voice data when feeding acoustic samples into machine learning pipelines.
- Equitable Access: Ensuring that advancements in AI-driven voice tools remain accessible across diverse global healthcare settings.
A Global Research Community
The rapid evolution of AI in voice science is not the isolated achievement of a single laboratory or university department. It is the triumph of a connected, global network of researchers spanning every inhabited continent.
Prominent contributors driving this wave in the Journal of Voice include:
- Jérémie René Lechien (6 papers)
- Dimitar Deliyski (5 papers)
- Stephanie Zacharias (5 papers)
- Ahmed Yousef (4 papers as first author)
- Paavo Alku, Leonardo Wanderley Lopes, and Maryam Naghibolhosseini (4 papers each)
Supported by dozens of other international teams, these scientists are turning theoretical algorithms into life-changing diagnostic realities.
Future Outlook: The Path Forward for Voice Science
As we look toward the horizon, the Journal of Voice will remain the premier global platform for this evolving discipline. We remain fiercely committed to publishing rigorous research that shatters previous limitations while upholding the absolute highest standards of scientific integrity and peer review.
However, navigating the decade ahead will require deliberate, collective action across three key fronts:
- Thoughtful Engagement: We must learn what AI tools can authentically accomplish, recognize their blind spots and algorithmic biases, and use them to amplify human expertise rather than abdicate clinical judgment.
- Shared Ethical Frameworks: Dr. Hunter’s call for institutional guidelines cannot be answered by a single journal. It requires otolaryngologists, speech-language pathologists, computer scientists, and ethicists to forge unified standards of practice.
- Continuous Knowledge Sharing: The 161 AI papers published to date represent merely the opening chapter. Every clinician, researcher, and educator possesses unique insights that can enrich our collective understanding of the human voice.
Conclusion: An Extraordinary Moment in Time
For hundreds of millennia, the human voice has carried our triumphs, our vulnerabilities, and our very essence. Today, for the first time in human history, we possess technological instruments sophisticated enough to truly decode its profound complexity.

We now have the capacity to extend the reach of expert clinicians, to catch subtle pathological shifts before they transform into debilitating illnesses, and to democratize access to world-class voice care for underserved populations around the globe.
This is an extraordinary moment in time. The Voice Foundation and the Journal of Voice stand proudly at its epicenter. The next decade promises even greater, more astonishing discoveries—and we look forward to charting that brilliant future together.
About the Author
Ian DeNolfo is Executive Director of The Voice Foundation, which publishes the Journal of Voice. A graduate of The Juilliard School and The Curtis Institute of Music, he formerly performed as a leading tenor at opera houses worldwide before transitioning his passion for vocal artistry into arts administration and academic leadership at The Voice Foundation.